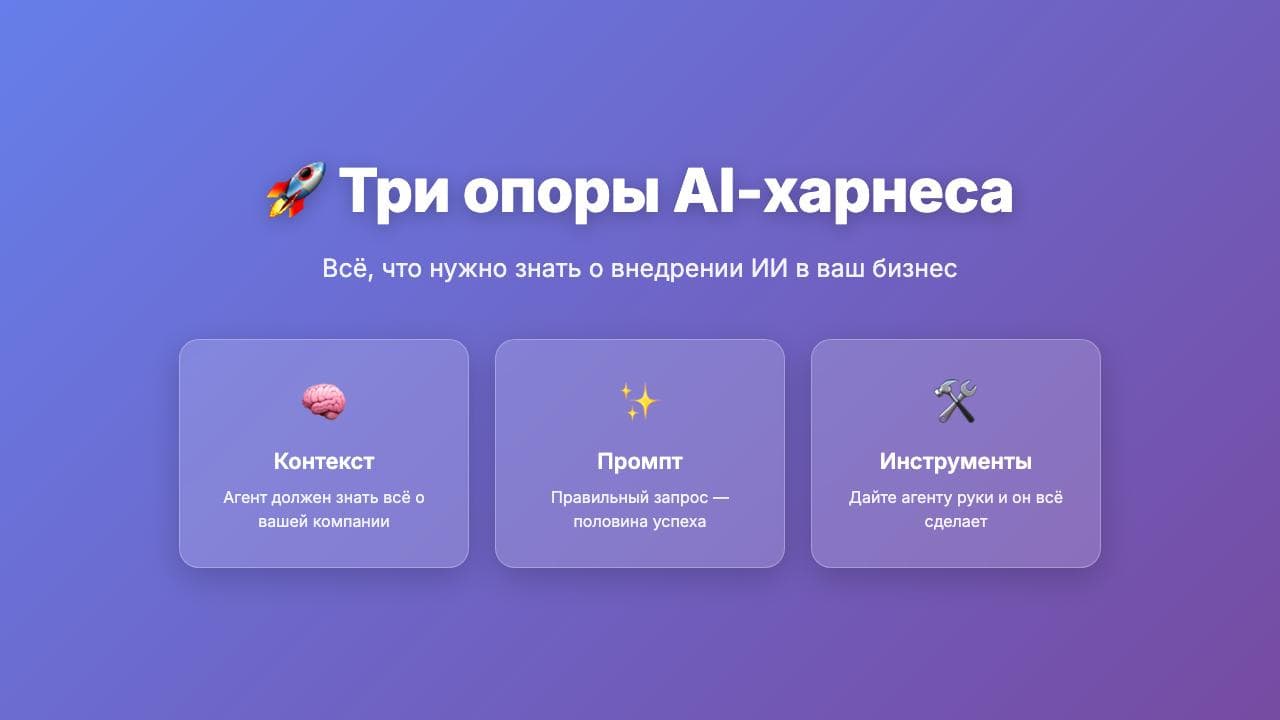
🎨 The same model, the same request - and almost always you get the same result.
Today at the presentation, I talked exactly about this: with the same input data, the result of working with an agent heavily depends on how you structure the process and prompts. The model is not a randomizer but a predictor of the most likely next token, so without external intervention, it always defaults to the same 'safe' option.
In an article by Anshu Chimala, a former Apple engineer and designer, this is illustrated in design: ask AI to 'make a presentation about AI' - and you almost certainly get a purple gradient, text on the left, image on the right. A scheme that is nauseating because literally every model generates it for every user.
Chimala suggests reintroducing external randomness into the process: generate a random alphanumeric string and use it as a seed for the design direction - a technique called 'String Seed of Thought' invented at Sakana AI. Plus, a separate agent-critic who evaluates the screenshots of the result as an art director, not as the author of the work itself. The result - a completely different outcome from the same initial data.
https://www.lennysnewsletter.com/p/how-to-turn-your-ai-into-a-world
#ai@rvnikita_blog #prompting@rvnikita_blog #design@rvnikita_blog #anshu_chimala@rvnikita_blog